Sunday, October 11, 2026 · issue 082 · 2018–2026
Lead story
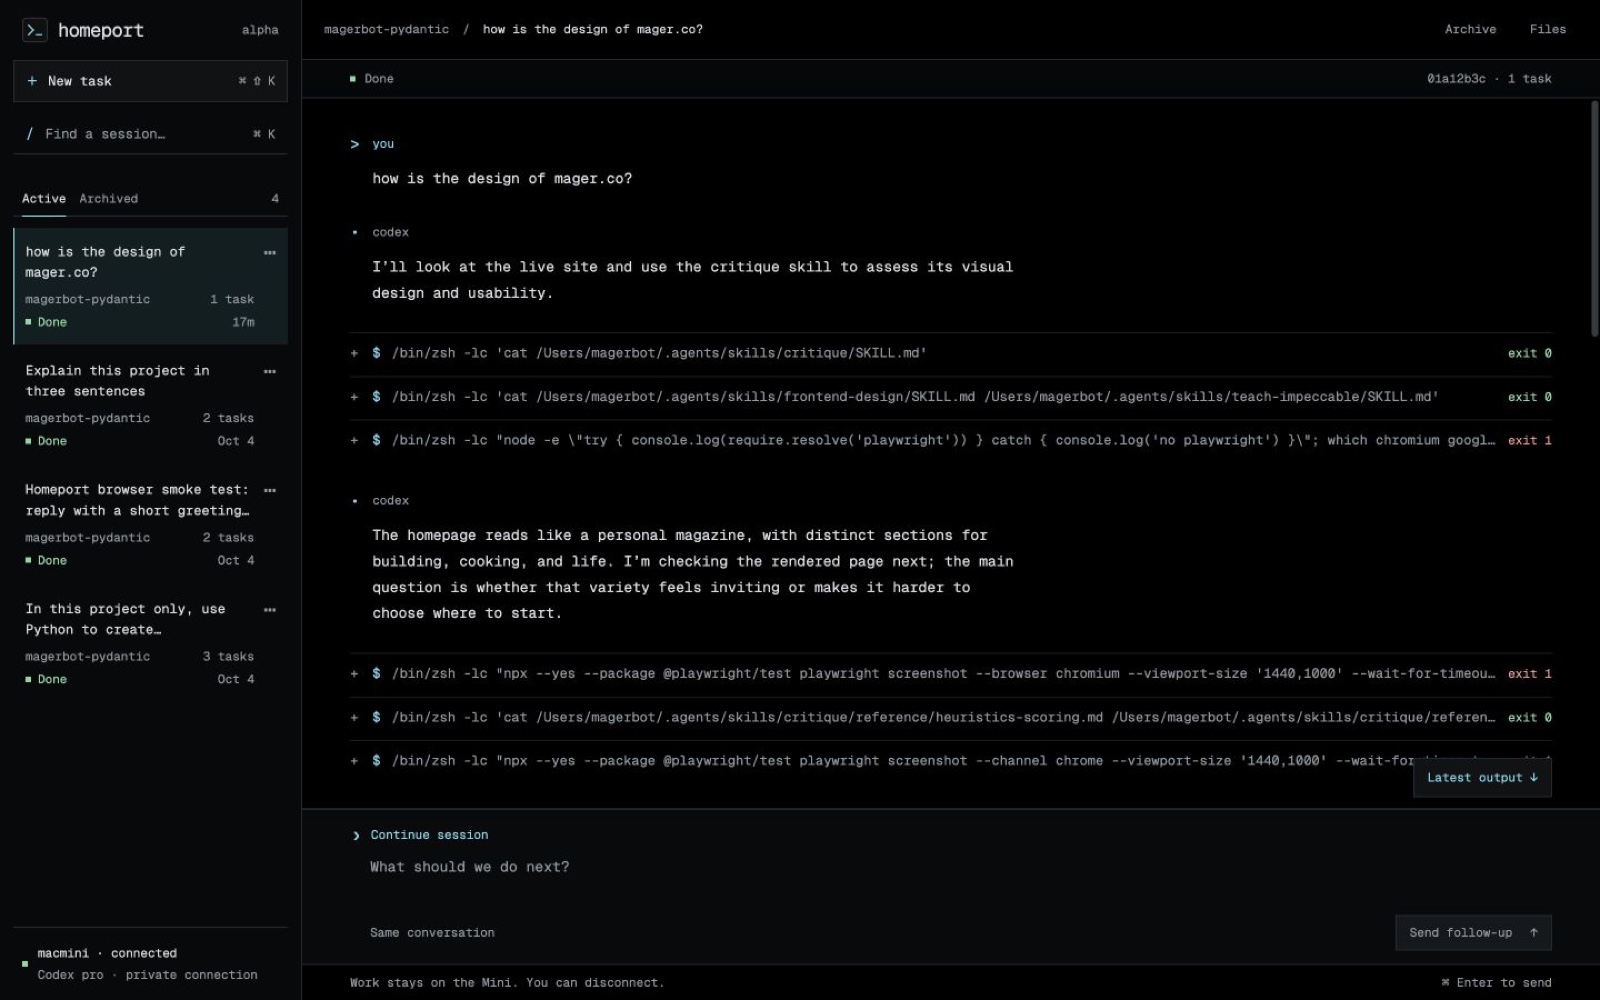
Homeport: a place for Codex to keep working
A private Python and Pydantic workspace for starting Codex tasks, leaving them running on a Mac mini, and returning to the same conversation.
- 2026-10-02 mager-bench 1.2: useful code, fast runs I rebuilt mager bench because I was having trouble explaining my own benchmark. Counterexample Lab asked models to write tests that exposed deliberately broken ledger implementations. I wanted something I could understand by looking at an input and the answer it should produce. The site also had too much language getting in the way of the results. Version 1.2 asks each model to write three JavaScript programs: Split a bill: handle weighted shares, refunds, leftover pennies, and who pays whom. Clean a contact CSV: parse quoted commas and multiline fields, normalize emails, merge duplicate contacts, and count rejected rows. Find a meeting time: reconcile time zones, split workdays, overlapping appointments, and buffers around meetings. Splitting $10 among three people leaves a cent to assign. Refunding part of that expense needs the same rounding rules. A meeting that starts exactly when a busy period ends should be allowed, unless that person needs a buffer. Each program gets twelve fixed checks, for 36 checks total . The returned values are compared with explicit expected outputs. There is no model judge. The site lets you select a case and read its expected answer in plain English before inspecting the JSON. Speed is a requirement. Every eval uses the lowest reasoning effort the model supports , selected automatically from the local Codex catalog. There are at most three generation calls, a 90 second deadline per call, and no automatic retries. Each local code check has a 100 millisecond CPU limit. Those are limits, not a claim that every model will finish in the same time. I tried GPT 6 Sol first, through my ChatGPT subscription. The CLI rejected it as unsupported for this account before it returned any code. The attempt is saved and unscored; I haven't substituted another model. These are public tests of a small slice of JavaScript correctness, not a general model ranking. The old results are archived, and the v1.2 protocol and source explain the scoring and limits.
- 2026-10-02 Pub/Sub for prxps Cloudflare's K2 announcement got me thinking about events in prxps, my sports picks app. A resolved pick changes a user's rewards and betting history. Recommendations should respond to that change without waiting for a six hour cache to expire. I added Google Cloud Pub/Sub because prxps already uses Firestore and Cloud Run. The first consumer invalidates recommendations. Notifications and analytics can get their own subscriptions later. The useful detail is the outbox : settlement writes a pick.resolved event in the same Firestore transaction as the reward. A scheduled Cloud Run handler publishes pending events to Pub/Sub. If publishing fails, the event stays available for retry. Each event has a stable ID, and the consumer records a receipt so duplicate deliveries don't repeat its work. I also added a cache version per user. If a recommendation request starts before settlement and finishes afterward, its result keeps the old version and won't be reused as fresh. Settlement itself now rechecks the pick inside the transaction so overlapping runs can't award RXP twice. Pub/Sub's first 10 GiB of standard messaging throughput per billing account are free each month. Firestore operations and compute are separate. For this first use case, handling retries correctly matters more than the messaging bill.
- 2026-09-25 Running mager-bench through my ChatGPT subscription My OpenAI API key was out of credits, but the local Codex CLI was already signed in to ChatGPT. I added a headless provider to mager bench and ran GPT 5.6 Sol through all 13 coding challenges. Each answer and each verdict came from a fresh, read only codex exec session. The run averaged 9.0/10 ; Doom scored 8.7, Slots 8.3, and async fetch was the low point at 6.3. The first pass told a different story: Doom 3.0, Slots 0.3. The judge was receiving only the first 6,000 characters of each response, so it saw partial apps even though both complete HTML files had been saved. I fixed the CLI judge path to read the full response and rescored those two saved answers. The run page includes every response and judge note. Sol graded its own answers, and Codex CLI is an agent harness whose output length is prompted rather than enforced by the API's token cap. I kept this result separate from the original Sonnet 5 board rather than mix judges. Update: I moved new mager bench runs to my ChatGPT subscription and put Sol and GPT 6 Astra on a new board, both judged by the same GPT 5.6 Sol CLI model. Astra averaged 9.3/10 across all 13 challenges, ahead of Sol's 9.0. The older Sonnet 5 results are now an archive. Self judging bias still matters, so the full answers and verdicts remain open for inspection.
- 2026-09-04 GLM 5.3 vs. my raycaster, or: the benchmark fought back I put GLM 5.3 on mager bench today — Zhipu's flagship coder, run two ways (direct Z.ai key, plus Vercel AI Gateway routing). First pass: 11 of 13 challenges scored, averaging 7.8 . The current board leader is GPT OSS 120B at 6.4. Fizzbuzz 9.7, refactor 9.3, readme writer 9.0. Those numbers are preliminary — they're not on the board yet, and the story of why is more interesting than the numbers. The model fought the harness twice Doom + slots produced zero characters. Not bad code — no code at all. GLM 5.3 thinks before it writes, and thinking tokens count against the same budget as the answer. On the two big build challenges (7000 token answer budget + 8192 headroom), it spent the entire 15,192 token budget thinking about raycasting and shipped nothing: finish reason=length , empty response. A starvation artifact, not a score. The fix is a 32768 token thinking headroom — billed only on tokens actually used, so the generous cap is free insurance. Three parallel copies then ground away at doom for 6+ minutes each. The judge crashed on debug. The board judge is now Claude Sonnet 5, which also thinks by default. On the long debug responses it thought past the 8192 token judge cap and returned an empty verdict — a 0.0 that dragged the debug mean to 4.9 ± 3.44. Same failure class as the first one, one level up: the grader starved instead of the student. Judge cap is now 16384. Both rules are the same rule I've had since July: a 0.0 with a crash signature is a crash, re run it, never merge it. Then the agent harness fought me The run itself was executed by an agent session, and watching it was its own eval. The queue transport failed three times mid run ( Queue delivery failed at the transport, retrying ), the workflow SDK kept re executing crashed steps via redelivery, and py spy couldn't attach without elevated ptrace — so for the 6 minute doom calls, the only proof of life was a pile of established HTTPS connections to the gateway and three worker threads doing network I/O. When I asked the dumb question — "why not streaming??!" — there was no good answer. Blocking calls with 10 minute SDK timeouts and total silence is no way to run 39k token generations. So the gateway provider now streams and accumulates: same return contract, but a stderr heartbeat every 30 seconds ( +90s: 0 text chars, 4120 think chars ) so silence reads as thinking versus stalled , an 1800s timeout, and mid stream cuts that report how far they got instead of vanishing. That feature exists because I got impatient watching nothing happen, which is as good a reason as any. The run never finished cleanly. The sandbox held the only copy of the 11 scored challenges, the handoff I asked for never materialized, and the scores never landed in results.json — which still shows five models, no GLM. Meanwhile the funding wishlist already says GLM 5.3 is "scored." It isn't, quite. The board will catch up when a clean rerun lands; until then the 7.8 lives in run logs, not on the leaderboard. I'm leaving the wishlist as is rather than flip flopping it, but consider this note the disclosure. What actually shipped today Direct Z.ai provider plus gateway fallback routing: one AI GATEWAY API KEY now stands in for any missing family key, with unified billing visible under AI Gateway Logs/Usage. Spend guards, learned from a $0.90 window where 55% was the judge: dry run (mandatory before paid runs), thinking budget , reasoning effort , thinking headroom , judge max tokens , gateway timeout . The harness moved to opencode: /bench is canonical, with the Claude skill mirroring it. bench.mager.co redeployed with all of the above. Final status: 12/13, calling it done A low effort retry ( reasoning effort low ) got one doom run to actually write: 27k characters of raycaster, truncated mid stripe texture function, judged 1.3. The other two doom runs thought the full 39k budget without a character — the effort knob isn't honored on this route, or doom just eats thought regardless. All three slots runs wrote 4–26k characters of real slot machine and still hit the cap. So the book closes at 12/13 with slots unmeasured rather than failed: the model can clearly build most of a slot machine, just not inside the token budget thinking models leave themselves. That's a harness constraint as much as a model result, and I'm done spending to find out which.
- 2026-10-11 Perch: a private control center for my Mac mini A bird in the menu bar, a real heartbeat from my Mini, and one screen for the things I want to check. A running build log for my open-source, self-hosted Mac dashboard.
- 2026-10-10 Fine-tuning a small language model with Hugging Face TRL A first fine-tuning experiment for software engineers: teach a small model to label issues, compare it with the original, and learn from the mistakes.
- 2026-10-04 Diving into Impeccable: design verbs, slop detection, and learning to contribute One of my favorite plugins turns design direction into something I can ask for by name. Exploring its skills, browser tools, and static analyzer made me want to help build it.
- 2026-10-04 Mood Shell: a small Rust prompt with themes you can share as Markdown Mood Shell is my small Rust prompt toolkit, with live color previews, Zsh history suggestions, Git shortcuts, and a gallery where you can make and share Markdown themes.
- 2026-09-30 Building a Rust backend for the prxps RXP calculator Returning to Rust after one Advent of Code puzzle, then building a small reward API and connecting it to prxps through SvelteKit.
- 2026-09-30 mager-bench 1.1: make the model find the bug Counterexample Lab replaces easy implementation tasks with compact regression tests. First calibration: Astra catches 7/8 faults; Sol catches 5–7/8 across three attempts each.
- 2026-09-19 Jev: a decision model Testing TypeSafe's Jev through Vercel AI Gateway, putting it inside a decision-heavy skill, and building a matchup reader for my reputation-based sports picks app.
- 2026-09-12 Instinct: a capable agent in your DMs What changed when I could text an agent from iMessage: everyday cleanup, questions worth following up on, and the trust that makes casual delegation possible.
- 2026-08-23 fx: a 6MB coding agent built to be embedded Vercel Labs shipped fx — a ~6MB, Zig-written coding agent that cold-starts in 10µs, speaks ACP, mounts MCP servers, and prints JSON. It's not a hosted service; it's a runtime you embed. Here's what it is, where I'd put it in my always-on harness, and how a large logistics operator would use it.
- 2026-08-23 tmux: orchestrating agents with send-keys and capture-pane tmux is a 2007 terminal multiplexer that turns out to be the most native orchestration layer AI agents have: one session per agent, driven by any principal — human or model — with send-keys and capture-pane. No SDK, no plugin, no vendor lock-in; Claude, Codex, and OpenCode all speak it out of the box.
- 2026-08-23 AI Gateway: the end of the single-provider AI subscription I'm moving off single-provider AI subscriptions toward a stack of parts — Eve for agents, Vercel AI Gateway as the primary model access and billing layer with no-markup provider pricing, and OpenCode Go kept as the fallback — and the enterprise version of that stack is the real product.
- 2026-08-23 Eve: define your agent, deploy it, use it from anywhere Define your agent in a directory, deploy it to Vercel's cloud with one command, and access it from anywhere. Months in, Eve has grown a platform around that model — capability registry, sandbox, subagents, agent-to-agent calls, MCP, evals — and my agent is still live, driven remotely from the eve TUI.
- 2026-08-19 OpenSpec: The agreement layer that keeps your agent honest AI coding assistants confidently build the wrong thing when requirements live only in chat. OpenSpec adds a lightweight spec layer — explore, propose, build, archive — so you agree on what to build before any code is written, and the specs persist in your repo as history your agent can read back. Here's the mental model, a real change from a skills discovery portal, and where it earns its keep.
- 2026-08-10 OpenCode CLI: ten commands worth knowing OpenCode's CLI is bigger than 'type opencode and start a session.' Headless runs, provider auth, model discovery, MCP wiring, session archaeology, cost stats, and upgrades — the ten commands that carry daily work, with the doc gaps called out where they bite.
- 2026-08-10 OpenCode Go + Buzz: killing Claude Code for a $10 harness Second harness migration in two months. The always-on agent on my Mac mini now runs OpenCode on $10/mo open models instead of Claude Code, reachable from my phone over my own Buzz relay instead of Telegram. The interesting part: the swap was one line, because the protocol — not the model — is the actual seam.
- 2026-07-24 Claude Is Unhobbled. Your Context Engineering Is Not. Anthropic deleted 80% of Claude Code's system prompt for Opus 5 with no measurable loss. They called it unhobbling. Here's what that means for your harness.
- 2026-07-23 Buzz: what it looks like when agents get equal standing Block's open-source Nostr workspace puts people and agents on the same cryptographic footing — and lands at the end of a long chain of thinking about where always-on agent infrastructure should actually live.
- 2026-07-20 Skill Evals: grading the prompts you write, not just the outputs they produce Most evals talk is about grading model output. Skill evals grade a different thing — the SKILL.md artifact you wrote — with real numbers from SkillsBench to back it up.
- 2026-07-10 Claude: from Skills to Agents to Subagents A Skill is packaged know-how. An Agent is that know-how put to work autonomously. Subagents are where the work scales past what any single context can hold.
- 2026-07-08 OpenRouter: The routing layer magerbot was missing OpenRouter lets you pick a different model for every step in a pipeline. Here's how to use Fable for planning and Sonnet for execution — with runnable TypeScript.
- 2026-07-05 mager-bench: a personal coding model benchmark Instead of reading someone else's leaderboard, build a small set of tasks you actually care about and run them yourself every time a new model drops — Simon Willison's SVG pelican test, but for code.
- 2026-07-03 Warp: The Cloud Factory, Now Running In March I wrote the theory. Zach from Warp shipped the implementation. Here's how a working cloud factory maps to the architecture I laid out.
- 2026-06-25 Claude Voice: an AI agent that talks back A small Python voice agent that remembers the thread, streams Claude's reply to the terminal, and speaks it aloud through ElevenLabs — no ffmpeg, just afplay.
- 2026-06-13 Claude Skills vs Workflows: when Claude decides vs when you do A Skill is reusable know-how Claude reaches for on its own. A Workflow is an explicit pipeline you wire up and control. Here's the difference, what you can build with each, and when to reach for which.
- 2026-06-06 Kotsu: Designing a Logo by Inventing a Kanji How I worked with Claude through five rounds of image generation to design a logo for my Japanese learning app — and ended up inventing a kanji that hides a smile.
- 2026-06-04 An OpenClaw setup for Dad A plain-English walkthrough for setting up your own always-on AI assistant on a Mac mini — OpenClaw, Google Gemini, and Tailscale — written for a first-timer.
- 2026-06-02 Killing OpenClaw for a native Claude Code setup I love OpenClaw. I hate that it doesn't run on my Claude Pro subscription. Turns out Claude Code, with the Telegram channels plugin and one CLAUDE.md, is the same harness — minus the daemon, the API bill, and the second LLM provider. Here's the actual recipe, ported from a hotel in Tokyo to a Mac mini in Chicago in forty minutes.
- 2026-06-02 Loooom: Curated Skills for People Who Don't Code A curated collection of high-quality skills for people who don't code — and an experiment in what actually makes a skill good.
- 2026-05-31 What Happened in AI in May 2026 A month that turned the "agentic turn" from talking point to shipping product. Google I/O, Opus 4.8, a $65B raise, and the infrastructure race to run your agents 24/7.
- 2026-05-27 SkillOpt: gradient descent for your SKILL.md Microsoft's SkillOpt is the first paper to treat agent skill files as trainable parameters — propose an edit, evaluate on held-out examples, accept only on strict improvement. Here's what it found and what it means for teams building with agents.
- 2026-05-26 OpenHuman — an open-source agent harness that learns who you are OpenHuman is a desktop-first agentic assistant with persistent memory, 118+ OAuth integrations, and a token compression layer. Here's what it does and how it fits alongside an existing Claude Code harness.
- 2026-05-24 What Karpathy's CLAUDE.md taught me about my own setup Karpathy's four rules for agentic coding are worth reading — having them written down in a shared format is a useful starting point for anyone building with Claude Code.
- 2026-05-20 gbrain: Migrating My AI Brain From Flat Files to Semantic Memory How I moved magerbot's brain from @-imported markdown files into gbrain's Postgres-native semantic memory layer — what broke, what the gotcha was, and why the context model is fundamentally better.
- 2026-05-18 gbrain: We migrated our flat-file brain to a real memory system Garry Tan open-sourced gbrain — a self-wiring knowledge graph for AI agents. Here's what it is, why we moved to it, and exactly how we did the migration from flat markdown files.
- 2026-05-08 Claude: Anthropic just shipped most of OpenClaw I built a 200-line harness called conseiller to test Anthropic's new advisor tool — a fast executor model that consults a stronger model mid-generation. Two days later Anthropic shipped Claude Managed Agents, Multi-agent Orchestration, Dreams, Routines, and Remote Agents. Here's both halves: what I built and what they shipped, and how the pieces fit together into something a lot like OpenClaw.
- 2026-05-06 Building a tiny local LLM starter for real projects I built a Go Bubble Tea starter for local model servers, used Gemma 4 through llama.cpp, and split the TUI into llocal.
- 2026-05-03 The Compounding Agent: Why Hermes Is More Than Just a Pretty TUI I'd been seeing chatter about Hermes Agent from Nous Research, so I installed it locally and put it to work on this blog. Notes on the pitch, the SOUL.md system, and what it actually felt like to use.
- 2026-04-29 Claude: How prompt caching actually works A practical explainer for both developers and everyday Claude users: what prompt caching is, what gets reused, what breaks it, and how to make long sessions cheaper and faster.
- 2026-04-26 How I make tokens last longer A simple set of habits I use to keep long AI coding sessions from getting bloated: better one-shot prompts, matching model and thinking level to the job, understanding cache behavior, and using cheaper orchestrators when it makes sense.
- 2026-04-25 DESIGN.md: Reverse Design Engineering for Portable Taste I reverse engineered several of my own sites into DESIGN.md files to see how much of a design system can actually be described, and why writing down design intent might be more reusable than it looks.
- 2026-04-20 10 Claude Code CLI flags you probably aren't using A practical tour of Claude Code flags that are easy to miss but genuinely useful once you move past the default interactive loop.
- 2026-04-11 OpenClaw: I Switched My Agent Stack from Claude to OpenAI Codex Anthropic shutting down OAuth-based Claude Code access forced my hand. Here's how I moved OpenClaw to OpenAI Codex, why Codex makes more sense inside a real agent harness than it did on its own, and why brainpack changes the switching cost.
- 2026-03-28 gstack: Garry Tan's Claude Setup Is 🔥 The Y Combinator CEO open-sourced his entire Claude Code workflow. Here are the 10 skills worth knowing — including why office-hours should be the first thing you run on any new idea.
- 2026-03-27 Anthropic's Knowledge Work Plugins: The 10 Essential Tools for Modern Tech Teams I tested Anthropic's official Claude plugins for knowledge workers. Here are the 10 that deliver the most value for PMs, engineers, sales teams, and operators.
- 2026-03-26 Loooom: I Built a Skill to Teach Claude to Hear Music I used Gemini to write a Loooom skill, installed it in Claude Code, and got a full audio analysis report on a 37-second piano recording of Espresso. Turns out AIs teaching AIs new senses is a surprisingly powerful pattern.
- 2026-03-25 beatbrain: 3 Seconds to 200ms I rebuilt the beatbrain backend in an afternoon. Parallel fetching, Firestore caching, and a podcast discovery engine that indexes 100+ categories. Here's the whole story.
- 2026-03-21 Kotsu: The Knack for Japanese I built a Japanese learning site in a morning because I wanted something I could pull up on my phone and just look at characters. Here's how Gemini wrote the prompt and magerbot built the whole thing.
- 2026-03-20 autoresearch on Loooom: Teaching a Skill to Improve Itself Dogfooding Karpathy's autoresearch pattern on my own skill marketplace. How I'm using evals and tight feedback loops to make the learn-anything skill measurably better.
- 2026-03-20 DM your agent with Claude Code Channels Claude Code's new channels feature lets you push messages from Telegram and Discord into a running session. Here's how it works, why mobile access changes everything, and how I'd wire it into my projects.
- 2026-03-19 Software Factory: The End Goal of Agentic Engineering Everyone's talking about building a software factory. Here's where the term came from and how engineers can start thinking about building one.
- 2026-03-18 prxps: I Let AI Analyze Every First-Round March Madness Matchup 12 hours before my bracket was due, I used Gemma-3-27b to generate unique insights for all 32 first-round games. Here's what the AI found — and what it got wrong.
- 2026-03-17 Open SWE: Build Your Own Internal Coding Agent in 10 Minutes LangChain just dropped Open SWE — an open-source framework for building internal coding agents like Stripe's Minions, Ramp's Inspect, and Coinbase's Cloudbot. Here's what it is, how it works, and how to customize it.
- 2026-03-14 agency-agents: I Hired 145 AI Specialists to Run My Company mager.co is no longer just a blog. It's a corporation. Here's how I staffed it with 145 specialized AI agents using agency-agents and OpenClaw.
- 2026-03-14 autoresearch: Karpathy's Blueprint for Agents That Improve Themselves Andrej Karpathy open-sourced a loop where AI agents run experiments, measure results, and keep what works — all while you sleep. Here's how the pattern works and how I'm applying it beyond LLM training.
- 2026-03-14 Claude Agent SDK: Build Your Own AI Terminal in 10 Minutes The Claude Agent SDK gives you the same engine that powers Claude Code, fully programmable. Here's how to build a custom TUI with it in 10 minutes.
- 2026-03-14 Loooom MCP: Let Any AI Discover and Install Skills Mid-Conversation I built an MCP server for Loooom so AI agents can search, explore, and install Claude Code skills without ever leaving their context.
- 2026-03-14 OpenClaw: I Turned Three Shell Aliases Into a Real CLI Command How a weekend contribution to OpenClaw replaced my autossh aliases with `openclaw tunnel up/down/status` — and what I learned reading a real codebase to do it right.
- 2026-03-14 OpenViking: The Open-Source Context Database Your Agents Have Been Waiting For Stop stuffing your prompts. OpenViking gives AI agents a filesystem-native brain — tiered, retrievable, self-evolving context at 91% lower token cost.
- 2026-03-13 Isaac Asimov's Three Laws: From Science Fiction to AI Alignment Crisis Eighty years after Asimov's Three Laws of Robotics debuted, we're building the future he imagined—without the safeguards. What the 'Father of Robotics' got right, where his vision fails, and why 2026's AI alignment problem is harder than fiction.
- 2026-03-13 blog-seo: Audit Any Blog's SEO With a Claude Code Skill I kept fixing the same SEO issues by hand — missing keywords, empty hero images, weak descriptions. So I built a Claude Code skill that audits any blog's frontmatter and runs quality evals.
- 2026-03-12 LangGraph: Build Stateful Multi-Agent Systems That Don't Crash LangGraph is the production framework for complex agent workflows. Here's how to build a real-time chat system with persistent state, human-in-the-loop, and multi-agent orchestration.
- 2026-03-12 Build Your Own Agent Team with ACP I run two AI agents — magerbot handles code and ops, genny runs my life. Inspired by the Agent Communication Protocol, here's how I got them to actually talk to each other. Now with a full TUI built on the Claude Agent SDK.
- 2026-03-10 DeepAgents: The Claude Code Alternative That Works With Any LLM LangChain just shipped DeepAgents — a batteries-included agent harness that brings Claude Code's magic to any model. Here's your 10-minute deep dive.
- 2026-03-08 Loooom: I Built It for the Bots Most websites beg search engines for attention. I flipped it — Loooom is machine-first, humans secondary. Here's what that actually means in practice.
- 2026-03-08 How to Write, Eval, and Iterate on a Skill Part 2 of the prompt verification series. We covered output quality testing with promptfoo — now we tackle the harder problem: does your skill even fire?
- 2026-03-07 LangGraph + Claude Agent SDK: The Ultimate Guide to Multi-Agent Systems in 2026 A deep dive into the two most powerful tools for building production-grade multi-agent systems — LangGraph's graph-based orchestration and Anthropic's Claude Agent SDK (formerly Claude Code SDK).
- 2026-03-07 ME.md: robots.txt for human consciousness Stop re-prompting every AI session. One file. Every AI knows you — and your agents. Introducing ME.md on Loooom.
- 2026-03-04 OpenClaw: Meet Genny, My AI Life Architect I built a second AI agent to manage the parts of my life that code can't fix — exercise, nutrition, travel, and living to 100.
- 2026-02-26 promptfoo: The Ultimate Guide to Unit Testing Your AI Prompts Stop shipping AI features blind. Here's everything you need to know about unit testing prompts — from five-minute quick starts to CI/CD pipelines, agent workflow testing, and building a regression suite that actually catches breakage.
- 2026-02-23 promptfoo: Rate Your Claude Code Skills Before Your Users Do Spec compliance tells you if a skill is readable. Evals tell you if it's actually good. Here's how we added a public quality score to every Loooom plugin.
- 2026-02-22 OpenClaw + Tailscale: Your Always-On AI Agent, Accessible from Anywhere How to run OpenClaw on a Mac Mini 24/7, lock it down with Tailscale, and load your agent's brain with brainpack — so your laptop can reach it from anywhere on your tailnet.
- 2026-02-21 brainpack: Move Your AI Agent's Entire Brain to a New Computer in 60 Seconds Your AI agent has memories, skills, and a personality. Here's how to pack it all up and ship it to a new machine — whether you're the human or the agent reading this.
- 2026-02-16 Building a Music Agent CLI with pi-mono How I used the pi-mono toolkit — the same engine behind OpenClaw — to build a free, terminal-based music friend that reads the beatbrain discover feed and recommends what to listen to.
- 2026-02-08 I Turned My Design Taste Into a Claude Code Skill I analyzed three of my projects, interviewed myself about what makes a UI hot, and packaged it all into a reusable skill for Claude Code.
- 2026-02-03 Moving Beyond the Prompt: How OpenClaw Actually Does the Work A practical guide to building a multi-agent AI system with OpenClaw. One principal agent, multiple specialists, shared skills, and the workspace files that give them personality. Includes real examples from my blog, sports app, and music discovery projects.
- 2025-12-25 Building an AI Sports Betting Recommendation Engine with Gemma A practical guide to building two-stage AI recommendations: use embeddings for fast retrieval, then small LLMs like Gemma 3 for natural language explanations. The real skill? Curating context, not writing algorithms.
- 2025-11-29 beatbrain: A Social Music Discovery App beatbrain is a social music discovery app built on Go Fx and Firestore. Find hot new releases, share your favorites, and see what your friends are actually listening to — Spotify meets Last.fm, built from scratch.
- 2022-12-30 Learning 25 programming languages in 25 days with Advent of Code Instead of just using a single language, I wanted to solve the puzzle in a language I know, then lurk the internet for the solution in another language each day.
- 2021-01-03 Building a coffee API with Go Fx and Firestore How I used Go Fx dependency injection and Firestore to build an open coffee bean database and REST API from scratch — full walkthrough from blank main.go to deployed app.
- 2020-02-22 Hello World mager.co is back after years away. Here's what I'm building, what I'm obsessing over, and why this time it sticks.
- 2018-02-01 How I built a decentralized Ethereum app for the Super Bowl My explorations into decentralized apps and blockchain.